Illumina Global Diversity GWAS Array🔗
| Name | Illumina Global Diversity GWAS Array (GDA GWAS) |
| Concatenated Data | genetics/genotype_microarray/GDA/ |
| Construct | GWAS, EWAS, Transcriptome |
| Study Visits | Samples are assayed from one sample (from parent and child), but may come from any visit (V01-V06) based on DNA yields. |
| Type | In-person Biospecimen collection |
| Quality Control |
|
Data users are prohibited from using HBCD data, including genomic data, to identify participants or their relatives. You accessed these data under a Data Use Certification (DUC) agreement in which you and your institution agreed that you would not attempt to establish the individual identity of any study participants or their relatives. You also agreed to adhere to a minimum cell threshold of 10 in any public reporting of data (i.e., publications, posters, or other presentations). Protecting participants’ anonymity demonstrates respect for them and minimizes their research-related risks.
The use of population descriptors in genetic research has been varied and inconsistent. The National Academies of Science, Engineering, and Medicine (NASEM) published a report on the use of population descriptors, such as ancestry, race, ethnicity, and geography, in genomics (). We encourage data users working with HBCD genomics data to consult the NASEM report to understand the past and current use of population descriptors in genomics research as well as current best practice recommendations when analyzing or reporting on HBCD genomic data. Race and ethnicity represent social constructs that are conceptually distinct from ancestry inferred from genetic data. Description of race and ethnicity variables in HBCD may be found in Basic Demographics.
Analysts using HBCD data have ethical obligations to minimize risks, including psychological, social, and economic risks, to research participants who generously provided their data. Risk minimization includes avoiding stigmatizing language when describing participants or the populations with which they identify, their phenotypes, or their genetic risks. It also includes carefully and clearly articulating limitations and caveats when reporting results and discussing how the results should and should not be interpreted or generalized.
Results generated from HBCD data may be used to guide policy (e.g., for social services, education, or public health interventions). Researchers should be aware of policy implications and controversies related to their research. Some approaches for ethically conducting and reporting research using genetic data are discussed in Meyer et al. (2023), Wrestling with Social and Behavioral Genomics: Risks, Potential Benefits, and Ethical Responsibility (The Hastings Center Report).
Researchers cannot control how others, including members of the public and policy makers, interpret scientific results we publish. However, we can take steps to minimize the likelihood our results will be misinterpreted or overinterpreted. In addition to clearly denoting limitations and caveats when reporting results, specific approaches for working with genomic data in this context are discussed in Martshenko et al. (2025), Social and Behavioral Genomics: On the Ethics of the Research and Its Downstream Applications (Annual Reviews Genomics and Human Genetics). For examples of brief documents that explain social and behavioral genomics for non-experts, see “FAQs on Human Genomics Studies” at https://www.thehastingscenter.org/genomics-research-index/.
The dataset includes two birth parents who are monozygotic twins (along with their respective families), which may complicate certain analyses. The participant IDs associated with this twin pair are under internal review and may be shared in a future update.
A total of 22 samples were excluded from data release (i.e., are not contained in the public release files) due to poor genotyping quality (i.e., SNP Missingness >10%), unexpected unrelatedness with no confirmed use of reproductive technology, unexpected relatedness (i.e., identical samples across adults), and sex check mismatch.
Instrument Details🔗
The genomic dataset generated from the Illumina Global Diversity Array (GDA GWAS) includes batch metadata and interlinked PLINK files (.bed, .bim, .fam) aligned to the GRCh38/hg38 Build. The dataset is provided in the release as concatenated data:
batch.info: Plain-text file mapping participants to genotyping batcheshbcd.bed(PLINK 1.9 .bed, distinct from UCSC BED): Binary genotype filehbcd.bim(PLINK 1.9 .bim): Variant information (chromosome, rsID, position, alleles)hbcd.fam(PLINK 1.9 .fam): Participant information
GDC Genomics QC Pipeline Analysis🔗
Along with general QC described above, genomics data are processed through the GDC Genomics QC pipeline (GDCGenomicsQC on GitHub) to perform additional checks. Summary results are outlined below. Key features of this pipeline include:
- Alternating filters for variant and subject missingness (10% followed by 2%)
- Sex checks
- Outlier detection based on the first two principal components derived from the genetic relatedness matrix using PC-AIR and PC-Relate (GENESIS)
- Classification of relatedness using IBD estimates from KING
Cryptic Relatedness🔗
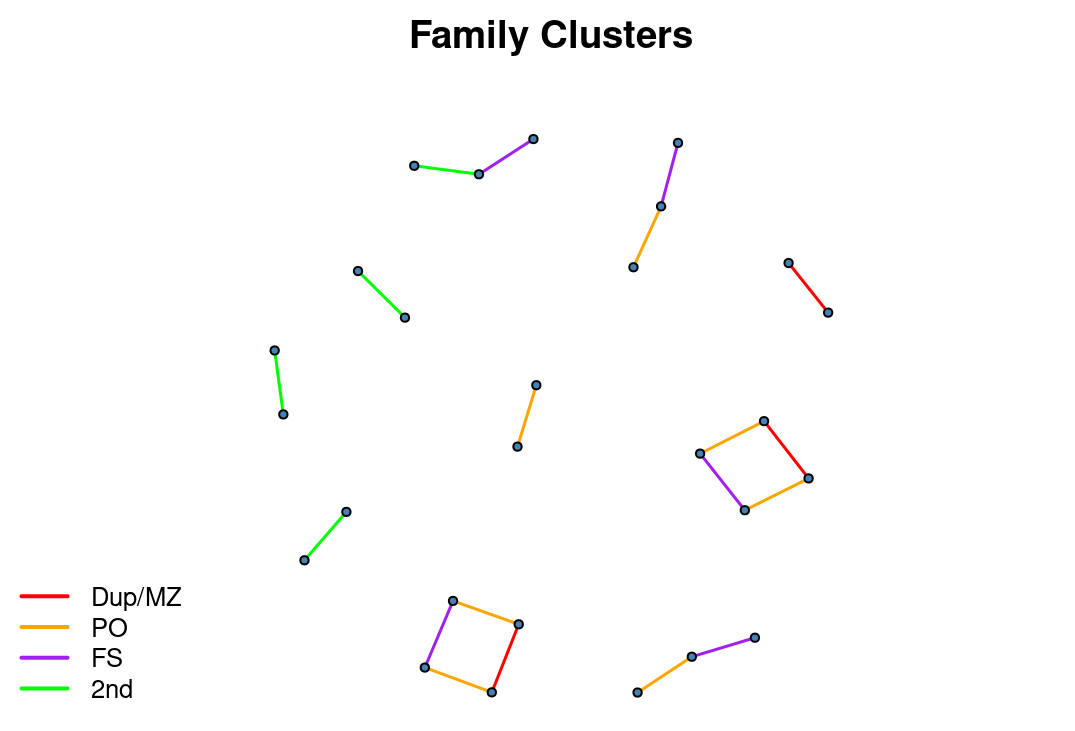
KING coefficient–inferred relatedness identified previously unreported familial relationships. The anonymized cryptic relatedness family graphs (right) show inferred relationships based on the following KING coefficient intervals (all visualized edges represent unreported relationships):
- [0.354, ∞] → Monozygotic twins or duplicate samples
- [0.177, 0.354] → First-degree (parent–offspring or siblings)
- [0.0884, 0.177] → Second-degree
- [0, 0.0884] → Unrelated
Genetic Ancestry-Based Clustering🔗
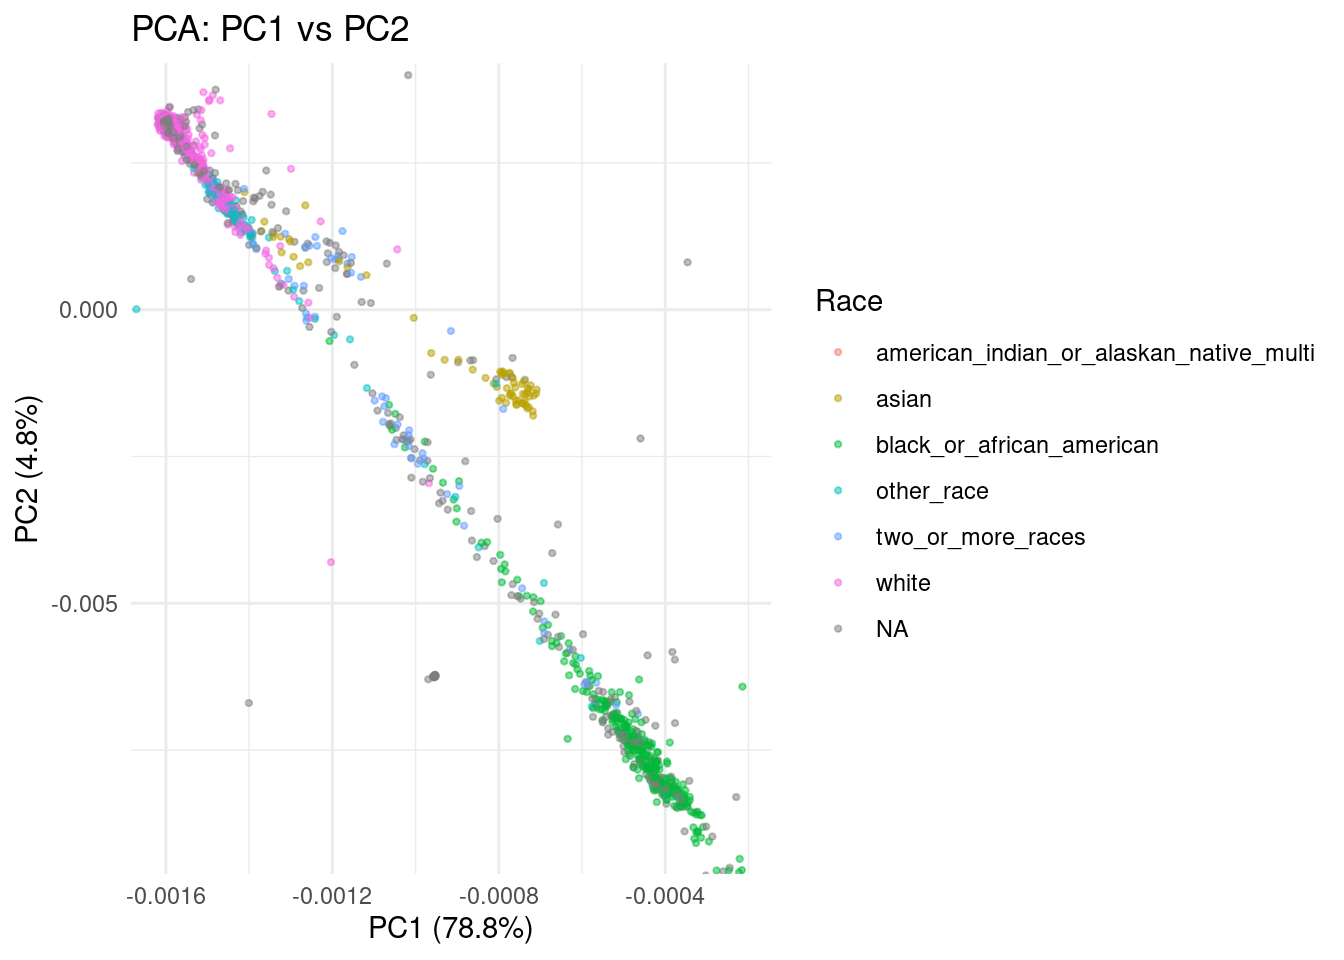
PC space derived from the first two PC-Relate components was visually inspected to assess clustering by reported race. Reported race largely clustered within the first two genetic principal components:
Committee on the Use of Race, Ethnicity, and Ancestry as Population Descriptors in Genomics Research, Board on Health Sciences Policy, Committee on Population, Health and Medicine Division, Division of Behavioral and Social Sciences and Education, & National Academies of Sciences, Engineering, and Medicine. (2023). Using population descriptors in genetics and genomics research. National Academies Press. https://doi.org/10.17226/26902
Martschenko, D. O., Lee, S. S.-J., Meyer, M. N., & Parens, E. (2025). Social and behavioral genomics: On the ethics of the research and its downstream applications. Annual Review of Genomics and Human Genetics, 26(1), 425–447. https://doi.org/10.1146/annurev-genom-011224-015733
Meyer, M. N., Appelbaum, P. S., Benjamin, D. J., Callier, S. L., Comfort, N., Conley, D., Freese, J., Garrison, N. A., Hammonds, E. M., Harden, K. P., Lee, S. S.-J., Martin, A. R., Martschenko, D. O., Neale, B. M., Palmer, R. H. C., Tabery, J., Turkheimer, E., Turley, P., & Parens, E. (2023). Wrestling with social and behavioral genomics: Risks, potential benefits, and ethical responsibility. The Hastings Center Report, 53 Suppl 1, S2–S49. https://doi.org/10.1002/hast.1477